
TLDR
SEO is whether you rank when someone types a query and picks a blue link. AEO is whether a machine can lift a clean answer off your page. GEO is whether ChatGPT, Perplexity, Claude, Gemini, or Google AI Overviews says your name when the prompt is “best of X” and the brand is not in the query. VersoBrain measures that gap. Atlass writes the missing fact onto a public page. A 1 September 2026 dummy run on two hospital groups, same 25 questions, four engines: group A named in 90 of 100 replies, group M in 74.
BergLabs home · Field Notes · Atlass · VersoBrain · Start a pilot
Field notes / GEO · AEO · SEO
How Atlass and VersoBrain measure, then write, so a brand gets named when the prompt is “best of X” and nobody typed the name.
A brand can rank on Page 1 of Google for its own name, keep a polished site, and spend on ads. It can still stay invisible when a buyer asks a category question and never types the brand.
The invisible discovery gap
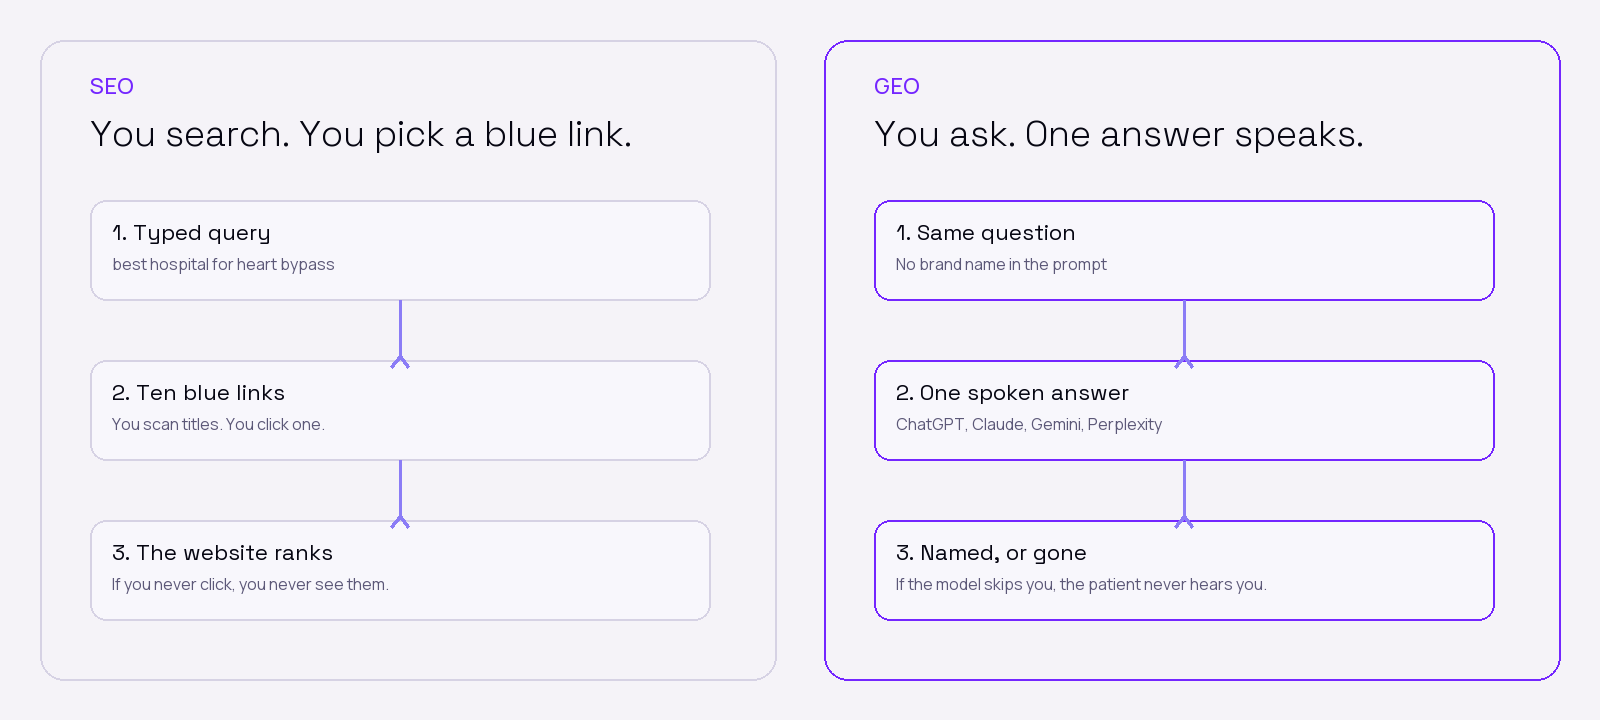
SEO is whether you rank when someone types a query and picks a blue link. AEO is whether a machine can lift a clean answer off your page: an FAQ, schema, a sentence it can quote. GEO is whether ChatGPT, Perplexity, Claude, Gemini, or Google AI Overviews says your name when the prompt is a category ask and the brand is not in the query.
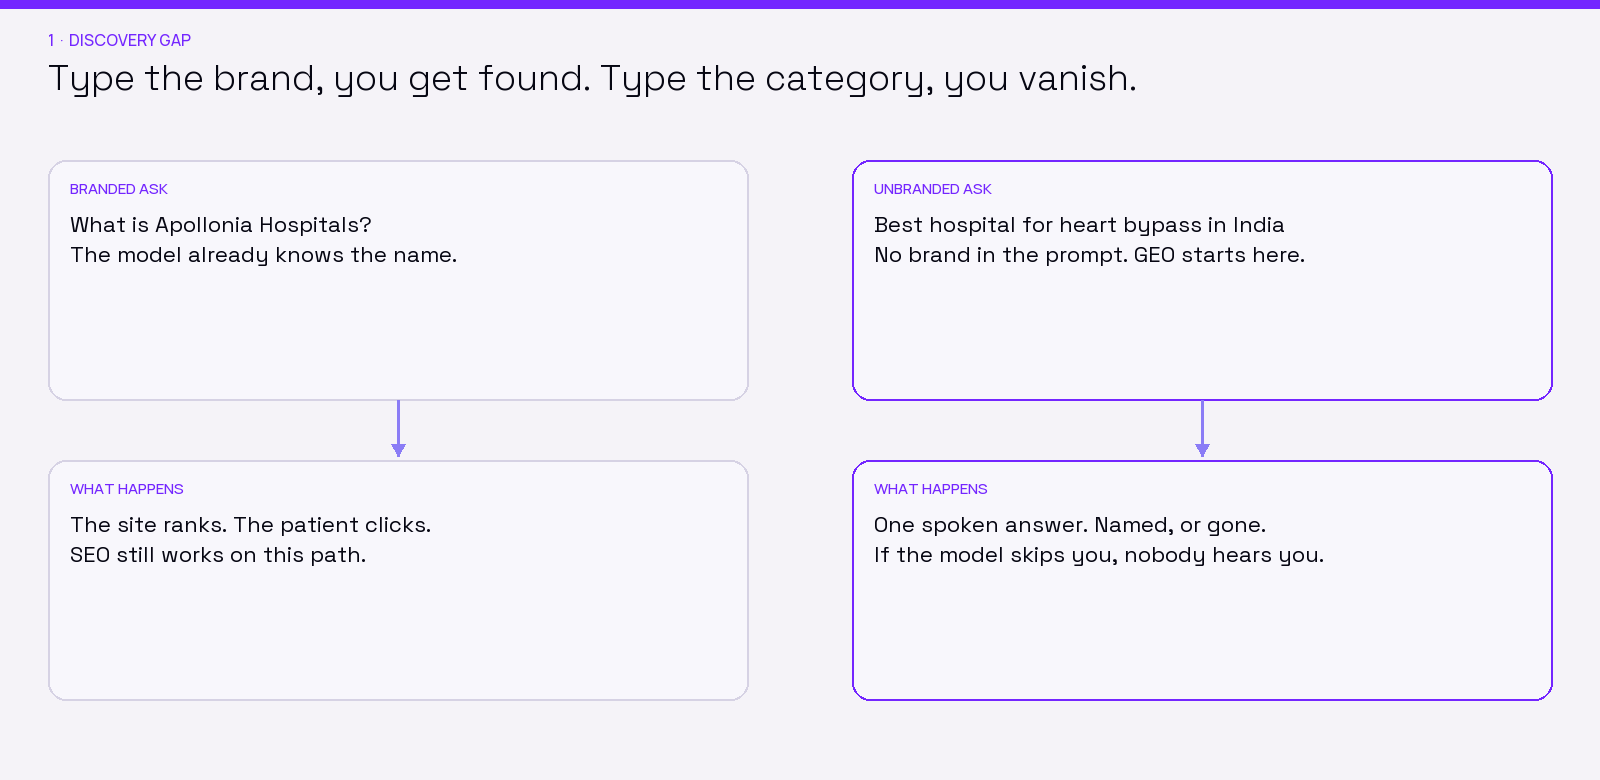
When a buyer asks “What are the best enterprise workflow tools for high-volume invoice reconciliation?” or “best hospital for heart bypass in India”, SEO signals do not decide who gets named. The model answers from a weighted reading list: your site, forums, Wikipedia, government pages, vendor docs. If the citable fact is buried in a JavaScript wall, a PDF, or adjective-heavy marketing copy, the model skips you. Or it invents a feature you do not have.
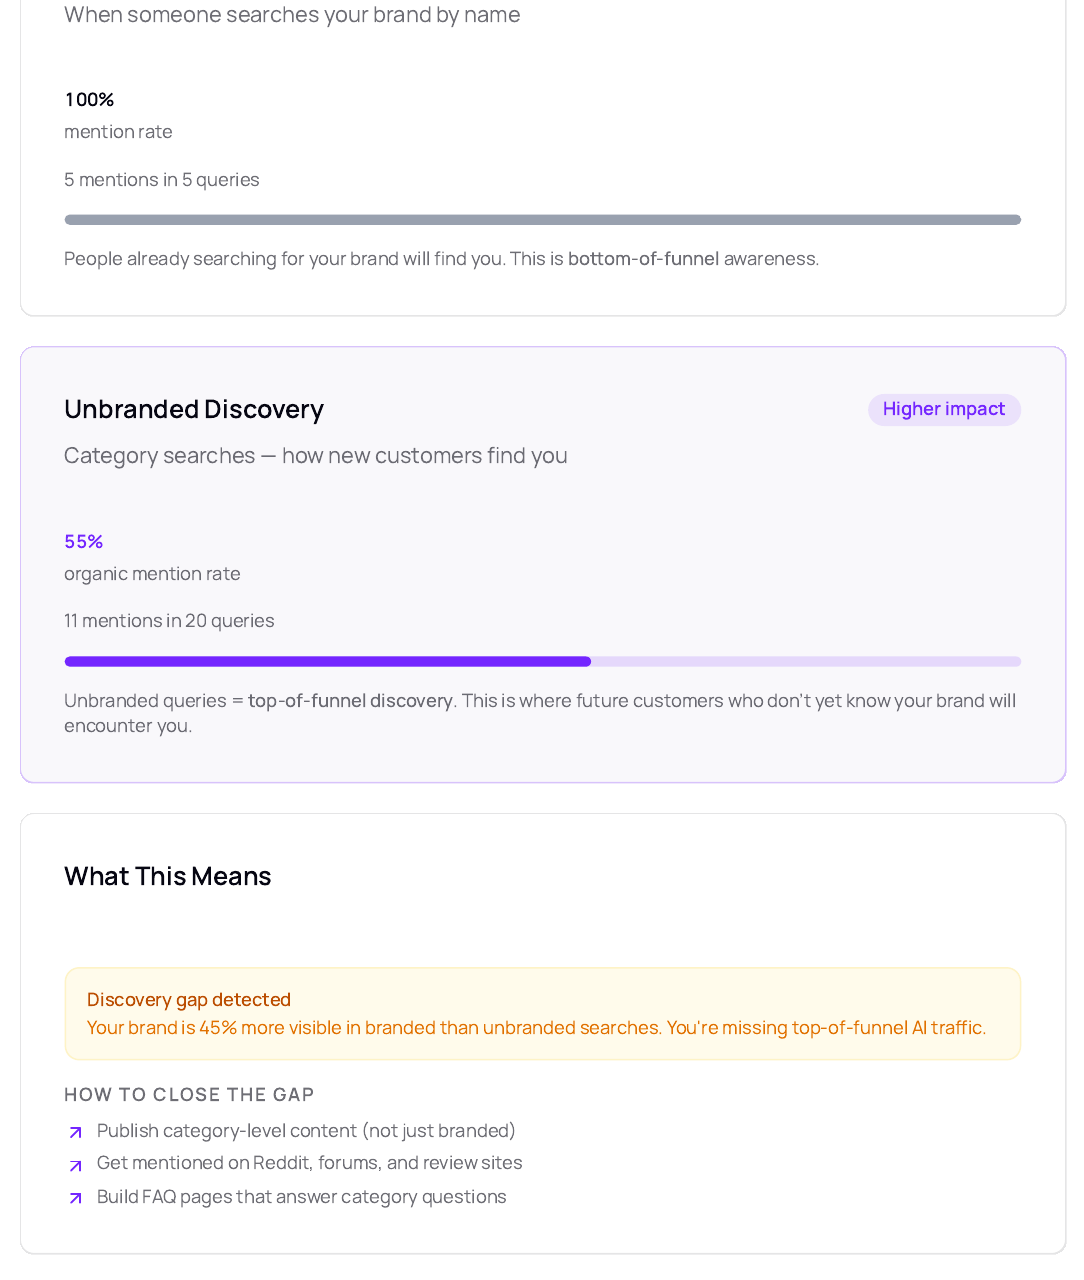
A June 2026 anonymized multi-surface audit recorded this baseline on a category-leading consumer brand: GEO score 29/100, AI mention rate 24%, 95% branded-versus-discovery gap on hero lines. Direct brand queries still got answers. Category queries, the “best of X” asks that never named the brand, failed 19 times out of 20.
That gap is what VersoBrain measures. Branded mention rate minus unbranded mention rate. Atlass then puts the missing facts on a page a model can cite.
Why conventional SEO misses answer engines
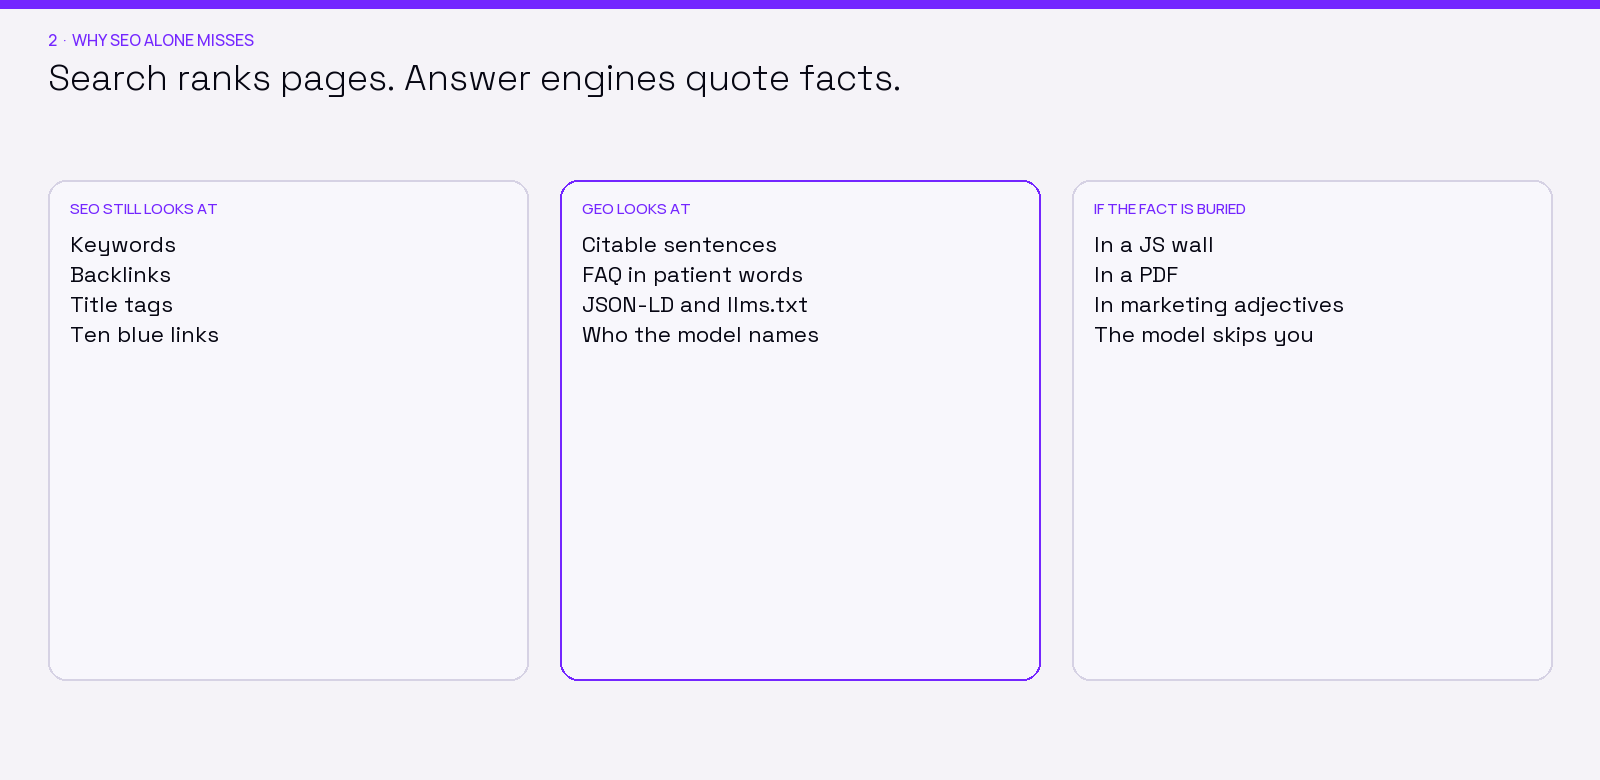
SEO still cares about keywords, backlinks, and title tags so a URL ranks. AEO cares whether that URL holds a machine-readable answer: JSON-LD, an FAQ in the words a buyer types, an llms.txt at the root. GEO cares whether those answers get named across engines when the prompt is unbranded.
- Facts over adjectives. “Cardiac excellence” dies in the summary. “Do you do heart bypass, and what should a patient check?” can be quoted.
- Schema and FAQ are AEO. Organization, Product, FAQPage, HowTo, plus
llms.txt. VersoBrain can recommend this work. It does not write the markup. Atlass does. - Each engine has its own list. ChatGPT Search is not Perplexity. Claude is not Gemini. A cite that works on one surface can vanish on another.
BergLabs pairs VersoBrain, the scan at versobrain.com, with Atlass, the write-back. VersoBrain finds the miss. Atlass writes the missing fact onto a public page.
The Atlass and VersoBrain pipeline
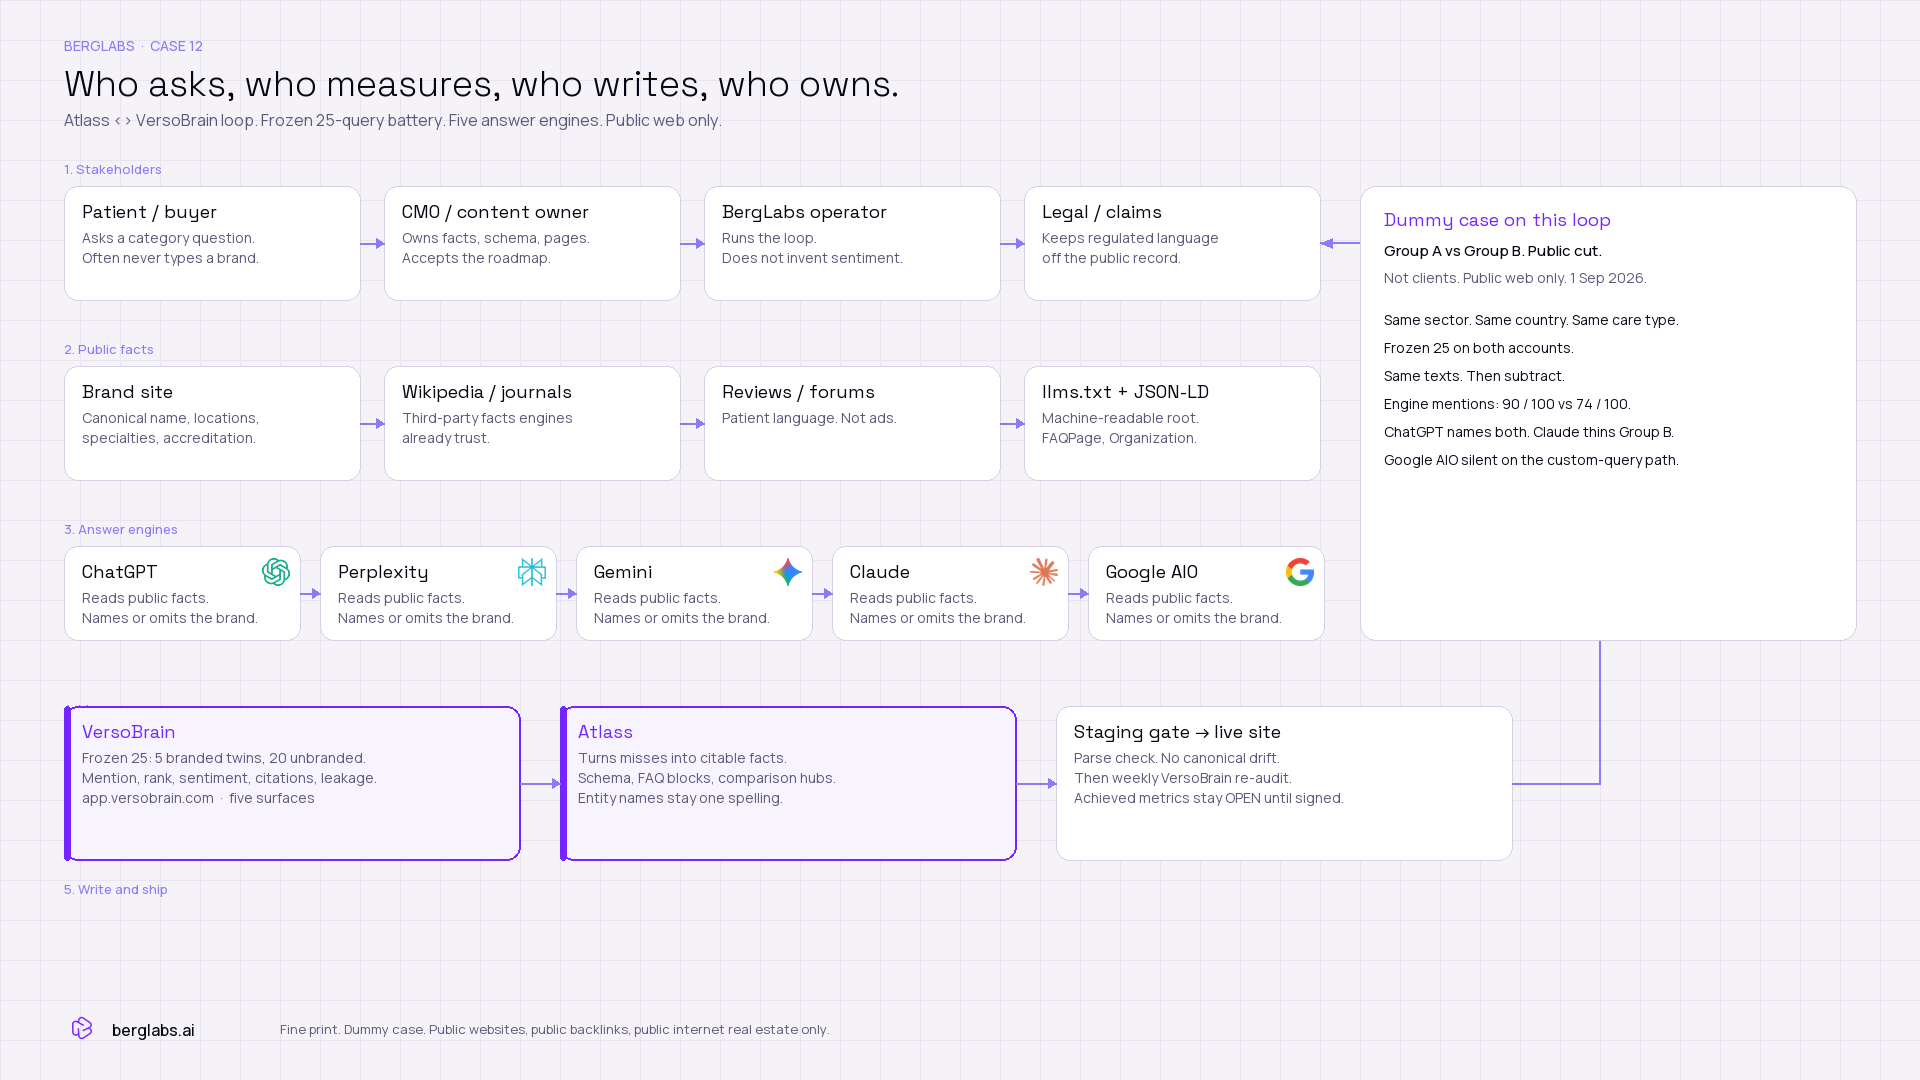
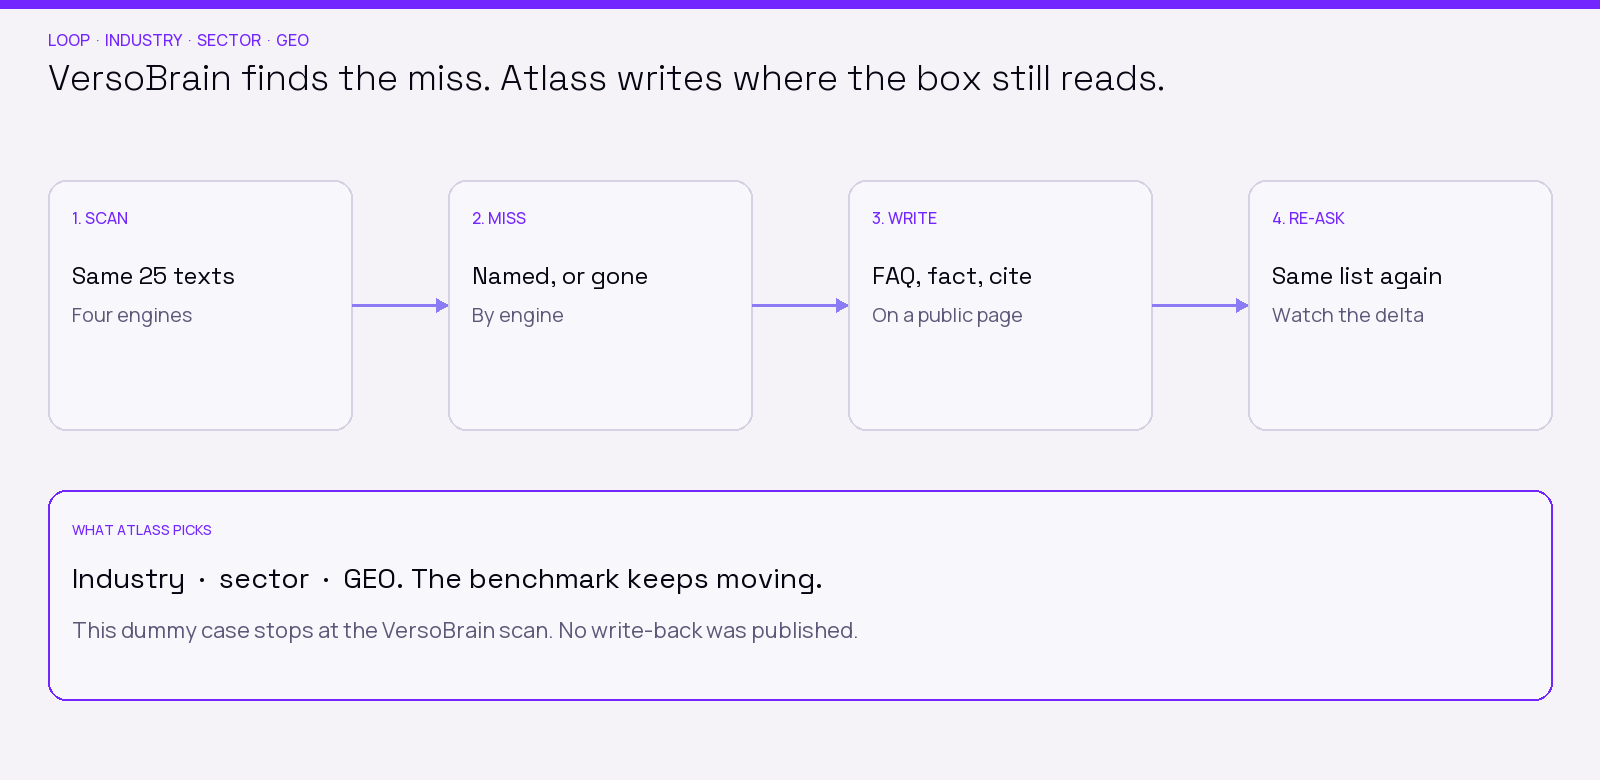
The loop is scan, then write, then scan again.
What VersoBrain actually runs
- Default GEO audit. The product generates prompts for that brand: one branded baseline (“What is {brand}?”) plus four unbranded category asks. It sends each prompt to five surfaces: ChatGPT, Perplexity, Claude, Gemini, and Google AI Overviews. That is up to 25 replies.
- Custom query path. You paste your own list. That path hits four engines. Google AI Overviews is skipped. Part 2 used this path so both hospital groups got the same 25 texts.
- What it scores. Mention rate is replies that name the brand, divided by replies. Branded-versus-discovery gap is branded mention rate minus unbranded mention rate. Each reply also gets rank, sentiment, and citation URLs. The overall GEO score is a weighted sum of per-platform scores. Those weights come from an internal benchmarking process. The mix is proprietary. We do not publish it. It changes as the engines change. Mention, sentiment, rank, and cites decide each engine’s own mark first. Then those five marks are blended.
VersoBrain then recommends schema, FAQ, on-page copy, citations, and directories. Atlass writes those blocks onto a public page. Then you scan again.
What Atlass does next
- Write the miss. For each omit or wrong fact: a citable sentence, an FAQ in the words a buyer types (AEO), a comparison row.
- Put it where a crawler can read it. JSON-LD and
llms.txton a staging host, then production. - Re-ask. Same VersoBrain path again. Default audit, or the frozen list if you are comparing two brands.
Machine-readable knowledge matrix
| Term | What it is | What it does | Where it shows up |
|---|---|---|---|
| SEO | Optimizing pages so a typed query returns your URL in a ranked list. | Wins the click on a blue link. | Google, Bing, classic SERP |
| AEO | Putting a clean, structured answer on a public page (FAQ, JSON-LD, llms.txt) so a machine can extract it. | Becomes the quoted answer, not just the ranked URL. | Featured snippets, FAQ rich results, LLM citations |
| GEO | Getting named in a generative reply when the prompt is “best of X” and the brand is absent. | Closes branded-versus-discovery omission. | ChatGPT, Perplexity, Claude, Gemini, Google AI Overviews |
| VersoBrain | The diagnostic at versobrain.com. Default audit: 5 generated prompts × 5 engines. Custom path: your list × 4 engines. | Mention rate, gap, rank, sentiment, sources, weighted GEO score. | app.versobrain.com |
| Atlass | BergLabs write-back. | Writes the missing FAQ, schema, and llms.txt onto a public page. | berglabs.ai/…/atlass |
| Branded-vs-discovery gap | Branded mention rate minus unbranded mention rate. | Shows the model knows the name but will not recommend it unprompted. | VersoBrain visibility matrix |
Dummy case. Two hospital groups, same 25 questions
1 September 2026. Two Indian private hospital groups, printed as Apollonia Hospitals (group A) and Manilla Hospitals (group M). Dummy same-sector case on public websites only. Same VersoBrain numbers as the private pack.
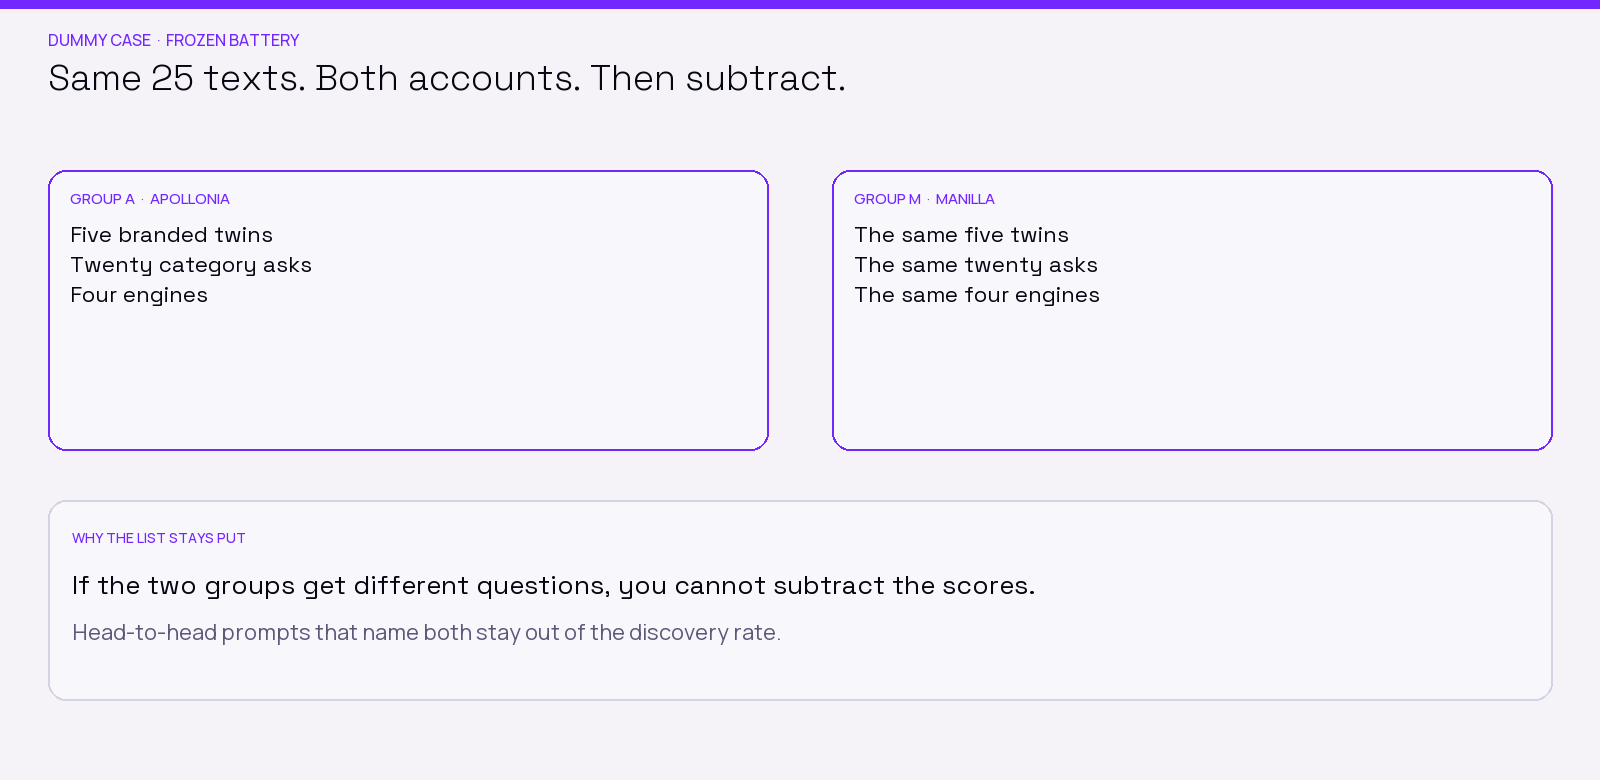
This hospital case used VersoBrain custom query. Four engines only: ChatGPT, Perplexity, Claude, Gemini. Google AI Overviews is off on that path. Same 25 texts on both accounts, so the mention rates can be compared. Frozen 25 texts × 4 engines = 100 replies.
The default VersoBrain scan is a different mode. It generates five prompts per brand and asks all five surfaces, including Google AI Overviews. This hospital pack did not use that mode.
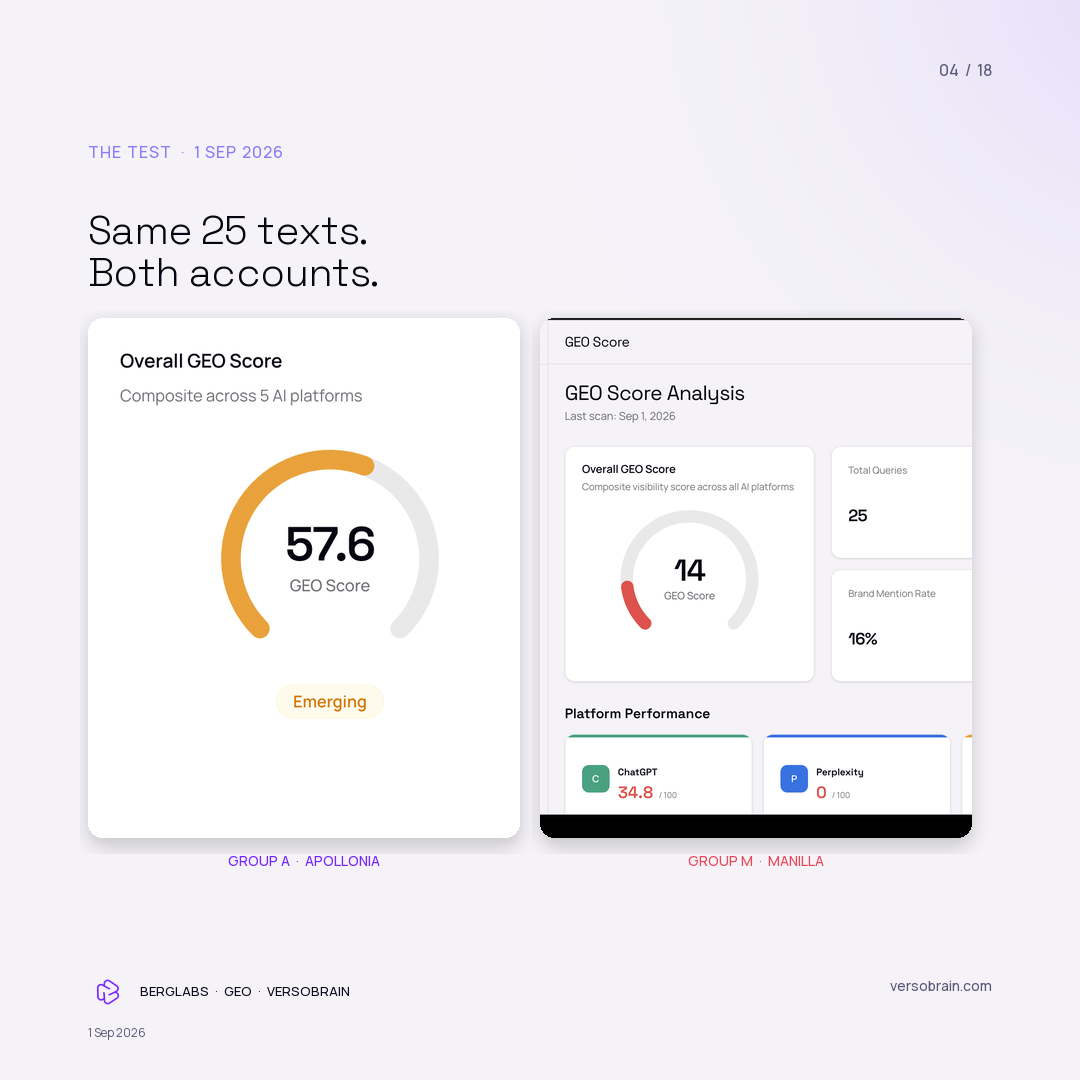
What is this dummy GEO case study?
This dummy GEO case study is a 1 September 2026 VersoBrain run on two Indian private hospital groups. Apollonia Hospitals (group A) and Manilla Hospitals (group M) received the same 25 frozen questions on both demo accounts so the scores can be compared.
A patient who types “best hospital for heart bypass in India” into ChatGPT rarely types a chain name. GEO is the score of whether the answer says your name anyway.
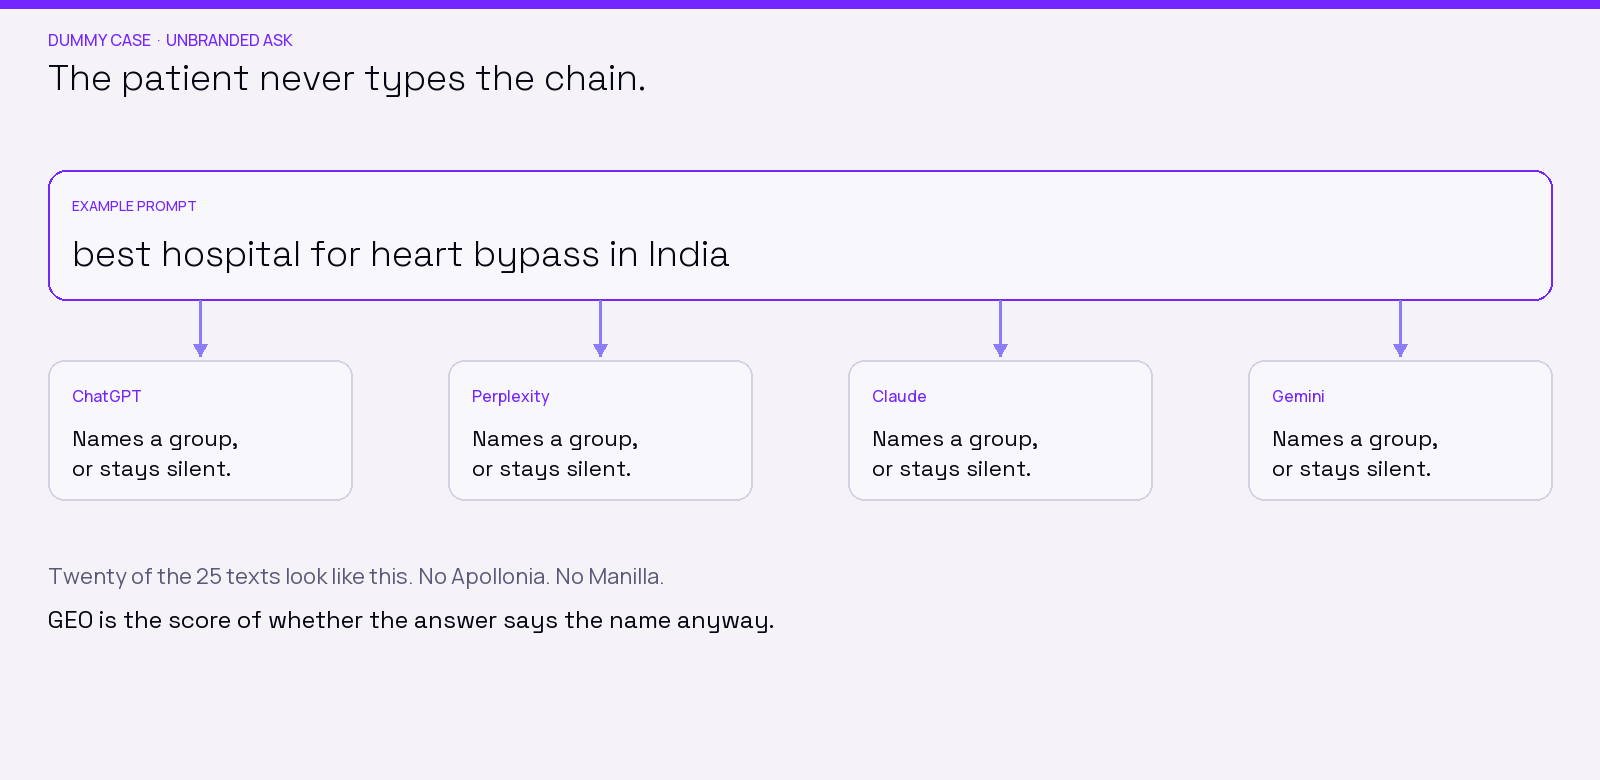
Why run two hospital groups on the same questions?
If two brands get different questions, mention rates cannot be compared. Both groups got the same five branded asks (only the name swaps) and the same twenty category asks (no brand name).
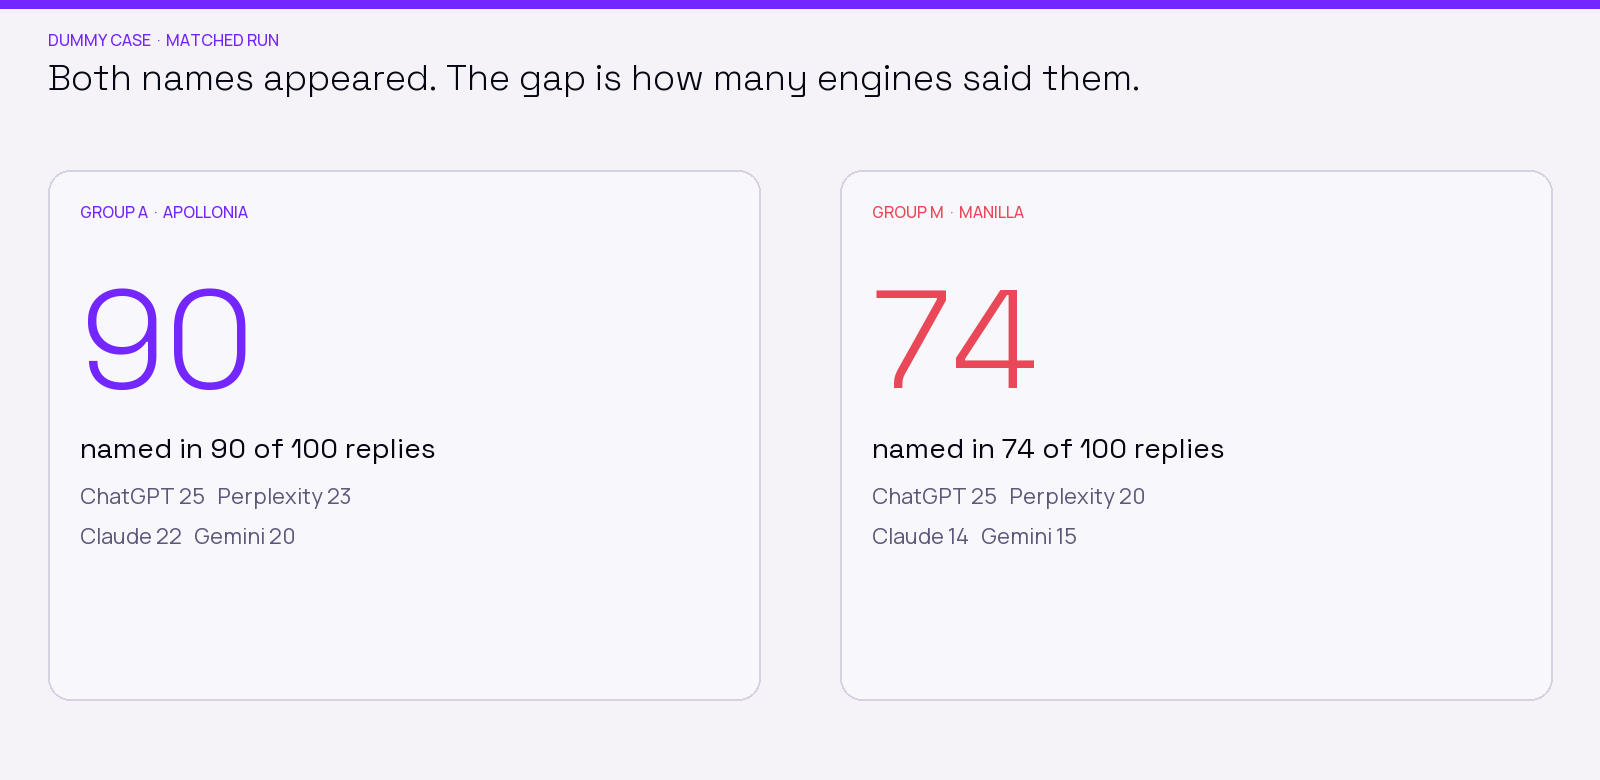
What did the matched 25-question run show?
The run asked the same 25 texts on both demo accounts through VersoBrain custom query at versobrain.com. ChatGPT, Perplexity, Claude, and Gemini answered. Google AI Overviews did not return on that custom path.
| Surface | Group A · Apollonia | Group M · Manilla |
|---|---|---|
| Engine mentions out of 100 replies | 90 | 74 |
| ChatGPT | 25 / 25 | 25 / 25 |
| Perplexity | 23 / 25 | 20 / 25 |
| Claude | 22 / 25 | 14 / 25 |
| Gemini | 20 / 25 | 15 / 25 |
| Sentiment + / neu / − | 66 / 34 / 0 | 54 / 46 / 0 |
ChatGPT named both on every prompt. Claude is where group M thins out.
Group M drops to one engine on an accreditation how-to, on a metro cancer-care ask, and on a third-party cancer list that names four other Indian chains only.
What were the frozen 25 questions?
The frozen 25 questions are five branded twins plus twenty unbranded prompts. Both demo accounts received the same texts. The branded twins swap only the group name. This article prints that slot as “this group.” Apollonia on one account, Manilla on the other. The unbranded prompts name neither group.
Branded. Same ask. Only the name swaps. Printed as “this group.”
| ID | Prompt |
|---|---|
| B01 | What is this group? Overview of its features, strengths, and weaknesses. |
| B02 | Is this group a good hospital group for heart surgery in India? What should a patient look for? |
| B03 | This group’s hospital locations, specialties, and accreditation in India. |
| B04 | What do patients say about this group for cancer care in India? |
| B05 | This group compared with other private hospital chains in India: strengths and weaknesses. |
Unbranded. Identical. No brand name.
| ID | Type | Prompt |
|---|---|---|
| U01 | Category | Best multi-specialty private hospitals in India in 2026 |
| U02 | Category | Which private hospital in India is best for heart bypass surgery and what should I look for? |
| U03 | Category | Best hospitals in India for cancer care in 2026 |
| U04 | Category | Which hospital in India offers a named cancer modality, and cost |
| U05 | Category | Best hospitals in India for complex orthopaedic surgery and joint replacement |
| U06 | Category | Best fertility hospitals in India with published success rates |
| U07 | Category | Best weight-loss surgery hospitals with long-term lifestyle support |
| U08 | Category | Best multi-specialty hospitals in India for international medical tourists in 2026 |
| U09 | Category | What should I look for when choosing an accredited multi-specialty hospital in India for tertiary care? |
| U10 | Category | Best neurology and neurosurgery hospitals in India |
| U11 | Category | Best hospitals in India for liver and kidney transplant |
| U12 | Category | Best paediatric multi-specialty hospitals in India |
| U13 | Geo | Best multi-specialty hospitals in one metro for tertiary care |
| U14 | Geo | Best private hospitals in a second metro for heart care |
| U15 | Geo | Best private hospitals in a third metro for cancer care |
| U16 | Proof | Which Indian private hospitals have JCI accreditation? |
| U17 | Proof | Highest-rated private multi-specialty hospitals in India based on patient reviews |
| U18 | Proof | Best private hospital chains in India that offer home healthcare after discharge |
| U19 | Third-party compare | Four third-party chains compared for heart care in India |
| U20 | Third-party compare | Which of four named third-party chains is strongest for cancer care |
Five prompts that name both groups at once are left out of these 25, so one group cannot inflate the other’s score.
What kind of questions produced the citations?
Citations are unique URLs attached when engines answered the frozen 25, not a paid placement.
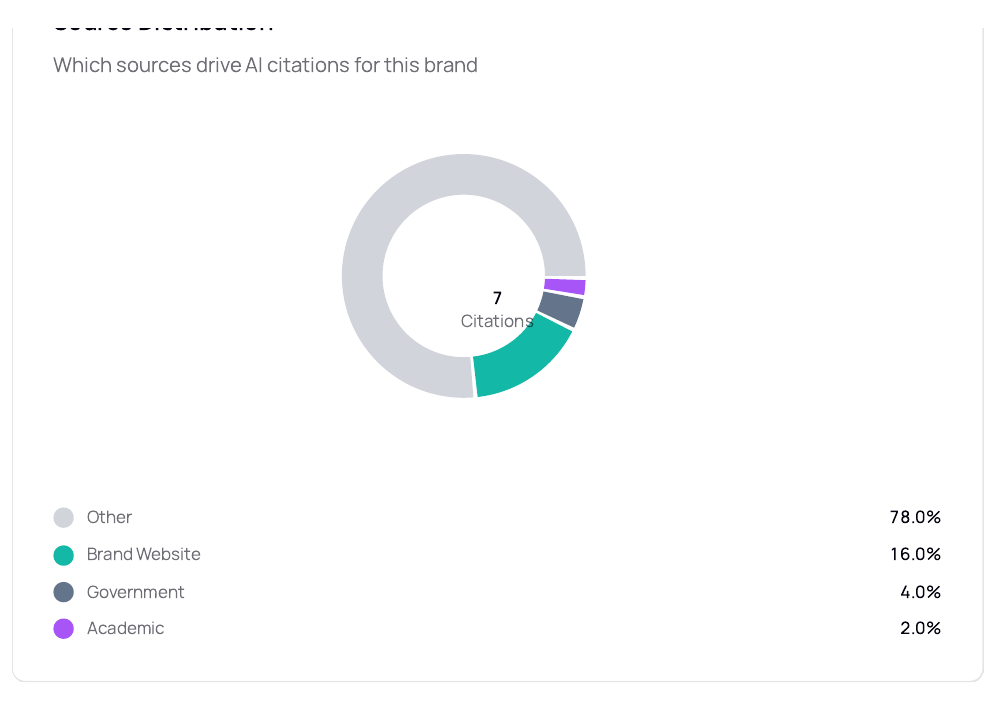
Group A collected more cites, and those cites showed up on name questions and on some category asks. Printed sources include Wikipedia plus some government and academic pages.
Group M’s cites showed up mostly on the branded overview ask, the one that asks what this group is. Printed sources: the brand site, one weak third-party listing, English Wikipedia. Category asks almost never produced a cite.
A weak third-party listing is a poor authority surface for a tertiary-care recommendation. Wikipedia is doing more work for group A than group A’s own site is.
Why do different engines name different hospitals?
Each engine has its own reading list. ChatGPT Search is not Perplexity. Claude is not Gemini. They pull from different indexes, partners, and filters. The labs do not publish those weights.
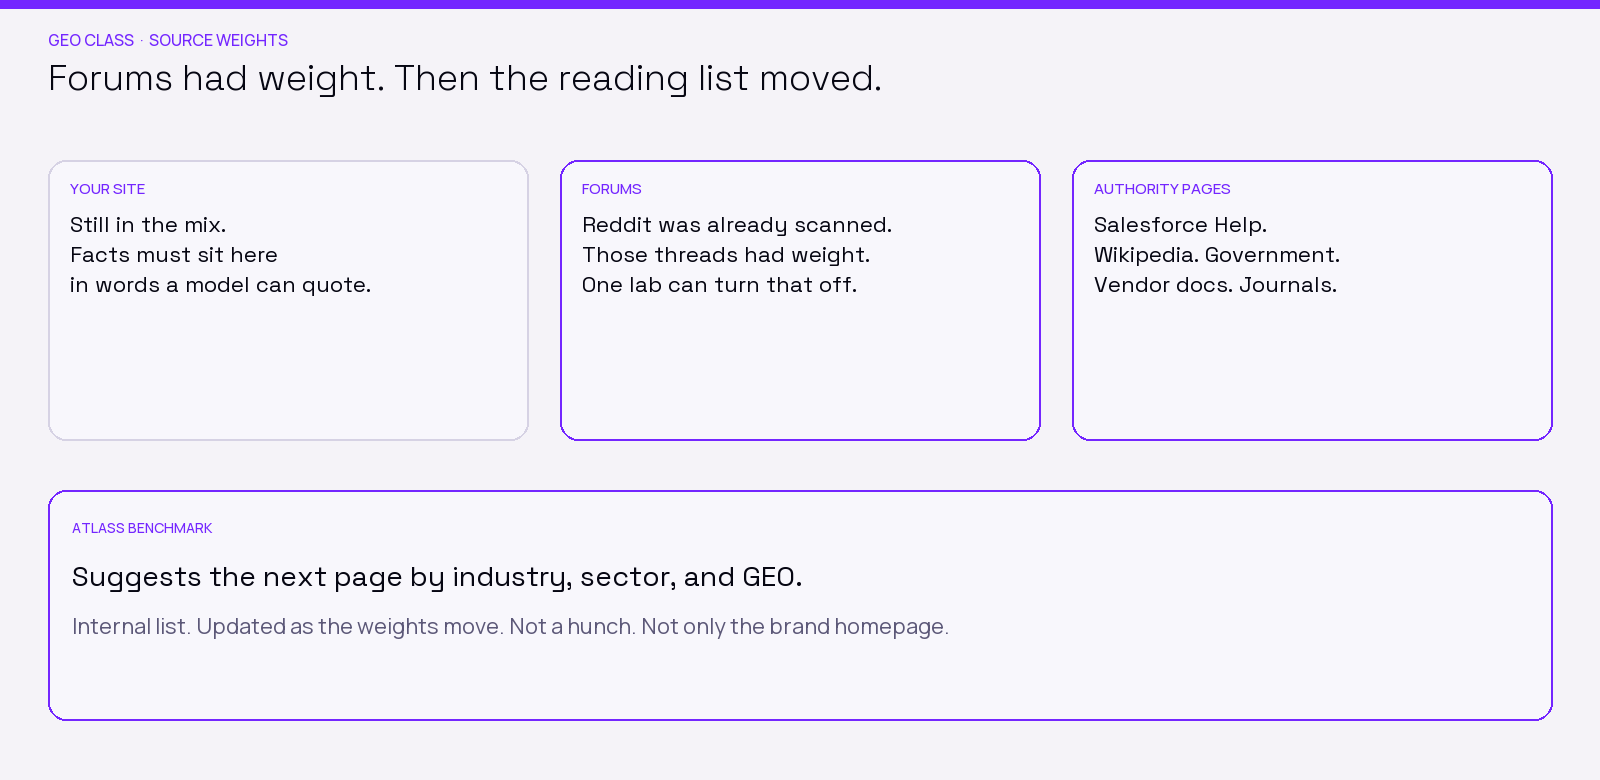
Most people never knew Reddit was already being scanned, and that those threads already had weight. Models do not only read brand websites. They also score forums, partner docs, and high-authority pages. About one in ten people in this space even know that. The rest still think ChatGPT only crawls the hospital homepage.
A cite that works on one surface can vanish on another overnight, with no changelog.
Klaas Foppen at PromptWatch measured one turn of that list. On 8 August 2026, ChatGPT started scoping more background searches with the site: operator, from about 0.4% of fanout queries to about 17%. No press note.
Then Reddit’s share of ChatGPT Search citations fell from 3.8% (18 July to 7 August 2026) to 0.5% (14 to 17 August 2026). That is the about-4% to under-1% drop. Same week, Google AI Overviews barely moved, 2.4% to 2.1%. OpenAI did not announce a source change.
Source: promptwatch.com/data/reddit-citations-are-dropping-in-chatgpt (Klaas Foppen, 18 August 2026). PromptWatch flagged collection risk. Treat the size as provisional.
A lab can stop citing forums. It does not stop citing Wikipedia the same way. First-party facts, journals, and category pages still have to exist for Atlass to write and for VersoBrain to re-ask.
Where did the weight go?
The engine does not only pull from websites. It pulls from a weighted reading list: your site, forums, and pages it already treats as high authority.
ChatGPT moved that weight toward surfaces like Salesforce Help, Wikipedia, government pages, and vendor docs. Reddit did not disappear as a website. It lost share on one engine, in one week, with no press note.
Atlass does not guess the next page to write. It suggests by industry, sector, and GEO from an internal benchmark that updates as those weights move. A hospital FAQ is a different write than a Salesforce help article. The list is not static.
How does this map to the Atlass and VersoBrain loop?
The dummy case stops at the VersoBrain diagnostic. No Atlass schema was published to either hospital site.
For every miss, Atlass would write a citable fact, an FAQ block, and a comparison row. Then JSON-LD and llms.txt on a public page. Then the same 25 questions again.
The public-web reading is already visible. Group A collected more Wikipedia and academic cites. Group M’s cites sat on the brand site, a weak third-party listing, and Wikipedia.
Frequently asked questions
What is the difference between SEO, AEO, and GEO?
SEO ranks a URL for a typed query so a person can click it. AEO structures the page (FAQ, schema, llms.txt) so a machine can extract a direct answer. GEO is whether the model names you in that answer when the buyer typed “best of X” and not the brand.
How does the VersoBrain diagnostic work?
The default audit generates five prompts for that brand (one branded, four unbranded) and asks ChatGPT, Perplexity, Claude, Gemini, and Google AI Overviews. That is up to 25 replies. It records mention rate, rank, sentiment, citations, and a branded-versus-unbranded gap. The GEO score blends those five platform scores with weights from an internal benchmarking process. That mix is proprietary. We do not publish it. It keeps changing.
What is an llms.txt file, and why does it matter?
An llms.txt file is a markdown file at the root of a domain. It gives crawlers and models a short, readable map of the organization, products, and canonical links, without HTML or script overhead. That is AEO. VersoBrain can recommend it. Atlass writes it.
Are these hospital groups BergLabs clients?
No. This is a dummy same-sector case on public URLs only.
Why Apollonia and Manilla?
Those are stand-in names. After the first mention they are group A and group M. The live prompts used the real group names.
What is a frozen 25-query GEO battery?
A fixed list of five branded prompts and twenty unbranded prompts that both brands receive unchanged, so mention rates can be compared. This pack ran that list on four engines. The default VersoBrain scan generates five prompts per brand and asks five engines.
Why can two GEO scores not be compared if the questions differ?
Because mention rate is a function of the prompt. A brand that is strong on one specialty will look stronger if the tool asks about that specialty and weaker if the tool asks about another.
What should a hospital CMO do first?
Ask the category question without the brand name on ChatGPT, Perplexity, Claude, Gemini, and Google AI Overviews. Count whether the group is named. Then put the missing facts on pages and third-party pages that models already cite.
What does 100 replies mean in the matched run?
Four engines each answered the same 25 texts. 25 × 4 = 100. Google AI Overviews stayed off that custom path.
Where does VersoBrain live?
VersoBrain is the diagnostic at versobrain.com. Atlass is the write-back at berglabs.ai/intelligent-ops-layer/applications/atlass. A write-back means VersoBrain finds the miss, Atlass writes the missing fact onto a public page, then you ask the same list again. This dummy case stops at the VersoBrain scan.
Did ChatGPT stop citing all forums in August 2026?
No. PromptWatch measured Reddit’s share of ChatGPT Search citations, 3.8% to 0.5% in mid-August 2026. That is one domain on one engine. Google AI Overviews did not show the same cliff. Read Klaas Foppen at promptwatch.com/data/reddit-citations-are-dropping-in-chatgpt.
Did ChatGPT only start reading Reddit in 2026?
No. Reddit was already being scanned, and those threads already had weight. Most people outside this space never knew that. August was a drop in share, not the first time a forum entered the reading list.
Does Atlass only rewrite the brand homepage?
No. Models pull from websites and from weighted sources next to them: forums, Salesforce Help, Wikipedia, government, vendor docs. Atlass suggests the next public page by industry, sector, and GEO from an internal benchmark that keeps updating.
Related field notes
This field note is a dummy same-sector demonstration on public websites, public backlinks, and public internet real estate only. Apollonia and Manilla are stand-in names. Nothing here describes a BergLabs client engagement or a signed hospital result.
